📌 Key Takeaways
Safe lift station recovery depends on clear event definitions, controlled pump re-entry, visible alarms, and tests for every requirement.
Define Each Event: The author recommends separate rules for outages, brownouts, rapid cycling, controller reboots, power transfers, and communications recovery.
Control Pump Re-Entry: The author recommends that controllers restart pumps only after they confirm stable power, safe levels, equipment status, and available capacity.
Decide What Survives: Teams should keep approved settings but deliberately reset temporary overrides and pending commands unless the project requires otherwise.
Preserve Operator Visibility: Power, control, alarms, communications, and timestamps recover separately, so operators need proof that normal service returned.
Test Every Requirement: Factory tests, site tests, and current manufacturer records should prove each event response and trigger retesting after system changes.
Resilience comes from explicit, reviewed, and tested recovery behavior.
Municipal operations, electrical, and controls teams will use these rules to review the restart specification that follows.
~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~
A sequence of operations may describe every pump start, stop, and alternation during normal service, then reduce power recovery to two words: automatic restart. That gap leaves multiple requirements undefined, partly because different stakeholders use "restart," "reset," "resume," and "recover" to mean different things. Which controller data survives? What state do outputs assume while the processor boots? How many pumps may re-enter service, and under which conditions? Which alarms persist or retransmit? What proves the station returned to normal?
There is no single safe restart sequence. Restart behavior depends on the approved operating philosophy, equipment, backup-power arrangement, wet-well conditions, motor and control constraints, site procedures, and applicable authority requirements. Government and industry guidance (such as the 2014 Ten States Standards for Wastewater Facilities, a regional design guide, and a 2000 US EPA pump-station fact sheet) have long treated power failure, alarms, emergency power, and restoration protection as recognized pumping-station design concerns.
A power event, as used here, means any electrical condition that interrupts, degrades, or changes the controller's supply or operating state. The matrix below converts those broad concerns into discrete, reviewable, testable decisions.
Define The Power Events Before Defining Recovery
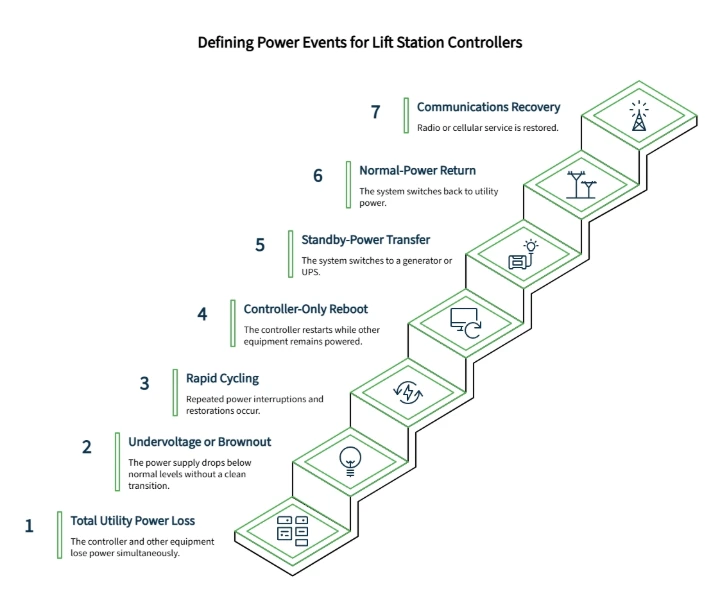
These seven power events—clean utility outage, sustained brownout, rapid voltage cycle, controller-only reboot, standby-power transfer, return to normal utility service, and communications recovery—are not interchangeable. Each can produce different controller behavior, different output states, and different alarm conditions. The controller, motor starters or VFDs, automatic transfer switch (ATS), generator, UPS, radio or cellular equipment, and alarm power source may not share the same power boundary, so a single electrical disturbance can affect each subsystem at a different time and in a different way.
Before assigning recovery requirements, define each event class with an observable entry criterion:
Total utility power loss. The controller, instruments, motor controls, alarm source, and communications equipment may lose power at different points. A total utility loss is distinct from an undervoltage condition that may or may not trip protective devices.
Undervoltage or brownout. Supply may become inadequate without a clean transition. Thresholds, dropout times, debounce settings, and ride-through duration are project and equipment specific. Verify documented ride-through for the exact model and firmware.
Rapid cycling. Repeated loss and restoration may create multiple boots, pump-start attempts, nuisance alarms or alarm storms, and confusing event chronology. One successful clean-outage test does not establish cycling tolerance.
Controller-only reboot. he controller may restart from a power dip, firmware fault, manual reset, or a watchdog timeout (an automatic hardware reboot triggered when the processor hangs) while instruments, motor controls, and communications remain energized.
Standby-power transfer. A generator transfer introduces a source change and possibly a voltage transient even when the outage is brief. ATS position, a stable source, and available generator capacity are distinct conditions.
Normal-power return. Transfer back to utility power is another controlled transition.
Communications recovery. Local control may be available before radio or cellular service returns.
Existing stations may carry undocumented panel modifications, legacy relays, mismatched as-built drawings, or incomplete firmware records. Map the actual power boundaries for the controller, starters or variable frequency drives, ATS, generator, UPS, instruments, alarm source, and communications equipment. For mapping power, ATS, generator, and alarm status signals to controller inputs, refer to the related article on lift station controller I/O planning.
Decide What The Controller Retains, And What It Must Deliberately Reset
"Nonvolatile memory" does not answer the retention question. Retained configuration means approved setpoints, alarm limits, equipment assignments, and sequence parameters that persist. Retained operating state means information about the condition immediately before interruption, such as lead assignment, active commands, overrides, acknowledgments, or temporary modes. A controller may preserve configuration while resetting its operating state, or it may attempt to restore both. The project must decide which objects survive and which clear, because blindly restoring every pre-outage condition can be as problematic as losing everything.
Organize the decision into three categories:
Typically retain:
Configuration and setpoints (alarm thresholds, timer values, calibration constants)
Runtime totals and counters (for maintenance tracking)
Event log and historian queue (where hardware supports it; capacity and overflow behavior are equipment specific)
Typically reset:
Temporary overrides and maintenance modes (restoring a pre-outage override may produce an unintended operating condition)
Pending commands (a queued output change from before the disturbance may no longer be appropriate)
Project decision required:
Lead/lag or duty assignment: retain, rotate, or reset depending on operating philosophy
Active alarms and acknowledgments: does an acknowledged alarm stay acknowledged, or revert to force operator re-evaluation?
Clock and time source: real-time clocks can drift or reset, making event chronology unreliable unless time behavior is defined
Communications state: local control may recover before the telemetry link, a condition called local autonomy, where the controller operates independently until remote connectivity restores
Define the real-time clock and time source separately. A reset, drift, or unrecorded resynchronization can obscure the order of power loss, controller boot, ATS transfer, pump command, and communications recovery.
Consider a hypothetical utility loss while one pump is running. The retained configuration (setpoints, alternation rules) should persist. The output state (the active run command to that pump) should not blindly resume; the controller must confirm stable power, level conditions, and equipment status before reissuing any command. The pre-outage operating state is context for the recovery decision, not automatic authorization to restart.
Manufacturer defaults are not an owner-approved operating philosophy, and they may change with controller model or firmware. Confirm retention, boot behavior, ride-through, output state, clock behavior, diagnostics, and event capacity against current exact-model documentation and testing.
Power-Event and Restart Requirements Matrix (excerpt)
Column | Utility Loss (hypothetical) | Controller Reboot (hypothetical) |
|---|---|---|
Event / transition | Total loss of utility supply | Processor restart without upstream outage |
Detection / entry criterion | Project-defined voltage/time threshold; ATS status | Watchdog timeout, manual reset, or firmware fault |
State to retain / reset | Configuration retained; operating state, overrides, pending commands reset | Configuration retained; alarms revert to unacknowledged; overrides cleared |
Output and pump response | Safety-reviewed transient output state until restart conditions met | Safety-reviewed boot state during initialization; re-entry per approved sequence |
Permissives / interlocks | Stable power; level in range; equipment not faulted; HOA in auto; generator capacity confirmed if on standby | Stable supply; level permissive; faulted equipment excluded |
Alarm / acknowledgment | Power-loss alarm on backup-powered path; alarms latched per project rules | Reboot event logged; pre-existing alarms restored as unacknowledged |
Event record / time stamp | Loss time, restoration time, each transition logged with synchronized clock | Reboot start/completion logged; clock accuracy verified |
Communications behavior | Local autonomy maintained; buffered events transmitted on recovery if supported | Communications re-established; queued events delivered if supported |
Recovery / return-to-normal | All pumps available or accounted for; alarms resolved or acknowledged; communications confirmed | Controller online; outputs confirmed; no unexplained alarm |
Verification / acceptance | Witnessed SAT per approved procedure; local and remote records compared | Witnessed test; event log reviewed for sequence and timing |
Owner, implementer, reviewer, witness | Owner: operations/electrical. Implementer: controls/panel team. Reviewer: manufacturer/AHJ where applicable. Witness: named in test plan. | Owner: controls/operations. Implementer: controls team. Reviewer: manufacturer/electrical. Witness: named in test plan. |
Populate the remaining event classes (undervoltage, rapid cycling, ATS transfer, normal-power return, communications recovery) using the same column structure.
Specify Pump And Output Re-Entry As A Controlled Transition
"Controller online" does not mean "pumps running." The generator or ATS supplies a power source; controller boot, output state, pump re-entry, alarms, and communications are separate requirements that recover on their own timelines.
Define what outputs do while the controller boots: a project-defined, safety-reviewed safe state prevents transient commands from reaching motor starters or VFDs during initialization. Once operational, pump re-entry depends on confirmed stable power, wet-well level and equipment permissives, hand/off/auto switch position, faulted or locked-out equipment exclusion, and (when on standby generation) available capacity for the next motor start.
Consider a hypothetical ATS transfer followed by generator availability. The ATS may complete its transfer and report "generator connected," but stable voltage at the controller and sufficient generating capacity for a motor start are separate conditions. The specification should distinguish source-available from capacity-available.
A real outage can occur while the wet well is high, a pump is already faulted, a hand/off/auto switch is in manual, maintenance is underway, or a portable generator is connected. Each concurrent condition changes which permissives apply and what "normal" recovery looks like. Automatic restart is not inherently more reliable; reliability does not determine safety or process acceptability without approved conditions, permissives, and sequencing.
Staged starts, restart priority, rapid-cycle lockout, and manual intervention criteria are project decisions shaped by the approved sequence, motor constraints, generator loading limits, and the site operating philosophy. For how wet-well conditions shape these decisions, see translating wet-well operating risks into controller requirements. For normal and abnormal duty-order context, see pump sequencing and setpoint requirements.
Preserve Alarms, Chronology, And Operator Visibility Across The Gap
Receiving a power-loss alarm does not prove that the controller recovered, that outputs returned to the expected state, that the event chronology is accurate, or that the station reached a genuine return-to-normal condition. Monitoring visibility and controller behavior are related but distinct scopes.
Local autonomy means the station can perform its approved local control functions without depending on the remote communications path. Return to normal means every project-defined recovery criterion has been satisfied. Neither term is proved by controller power alone.
Power, controller, communications, and operator awareness recover on different timelines. A useful specification accounts for each milestone:
Disturbance occurs
Controller transitions to safe state (local)
Power source stabilizes
Controller completes boot and resumes control availability
Communications link restores
Operator verifies return to normal
The alarm specification should define where the power-loss indication originates and how it is powered when the controller is down, whether alarms latch, whether acknowledgments persist through a reboot, and whether timestamps use a battery-backed or externally synchronized clock. When communications recover after local control, define whether buffered events transmit in order, whether duplicates are suppressed, whether a communications-restored message is sent, and how the operator confirms the remote view matches local conditions.
Monitoring platforms can provide useful visibility into these events. According to OmniSite's GuardDog page, users can set alarm triggers by input, create callout lists using email, text, and phone, and review historical data and reports. OmniSite also states that alarm-triggering state changes are logged and customizable callout notifications support multiple channels. These capabilities illustrate the kind of notification and historical visibility a project team may evaluate, but they do not establish persistence through an outage, store-and-forward behavior, or controller restart capability. Those behaviors require current product documentation and end-to-end testing for the exact equipment and service plan.
Alarm receipt proves that a message reached a defined point. It does not prove local control availability, correct outputs, pump re-entry, accurate chronology, or completed recovery.
Turn Every Requirement Into An Acceptance Test
A requirement without a corresponding test is difficult to enforce. A factory acceptance test (FAT) can evaluate logic, simulated inputs, outputs, alarms, and records, but may not reproduce field power boundaries, actual pumps, ATS behavior, field instruments, or a live communications path. A single clean-outage test does not cover unstable supply, repeated cycling, ATS transfer timing, communications-only failure, or a controller reboot without an upstream event. Define which event classes will be tested within the approved safe scope, and document the evidence for each.
For each matrix row, record the acceptance evidence:
Field | Description |
|---|---|
Requirement ID | Traces to the matrix row and column |
Precondition | Initial equipment, process, and safety state before the test |
Safe test method | Approved procedure with qualified personnel and applicable safety controls including lockout/tagout where required |
Expected local result | Output state, indication, and controller response observed at the panel |
Expected remote result | Alarm, notification, or event received at the monitoring endpoint |
Record / time-stamp evidence | Event log entries with timestamps; local-to-remote comparison |
Recovery criterion | Observable conditions confirming return to normal |
Witness | Named responsible party |
Result | Pass, conditional, or fail with documented basis |
Retest | Required after any change to logic, firmware, wiring, or configuration |
Distinguish which conditions can be safely reproduced during FAT and which must be deferred to a site acceptance test (SAT) with an approved procedure, coordination with operations, and applicable safety controls. Allocate clean power loss, controller reboot, ATS transfer, restoration, communications outage and recovery, and repeated cycling to the appropriate venue. Include brownout or unstable-supply behavior only when an approved method can evaluate it safely.
Any simulated power event requires an approved, site-specific risk review and procedure, qualified personnel, coordination with operations, applicable lockout/tagout or other approved safety controls, defined responsibilities, and an operating contingency that protects station service. Do not interrupt or manipulate live power, energized equipment, or active wastewater processes without explicit authorization.
Allocate proof among FAT, SAT, and manufacturer documentation. Name who accepts each form of evidence, and retest affected requirements after firmware, logic, panel, setpoint, communications, or power-system changes.
Five Questions To Resolve Before Approving A Controller Submittal
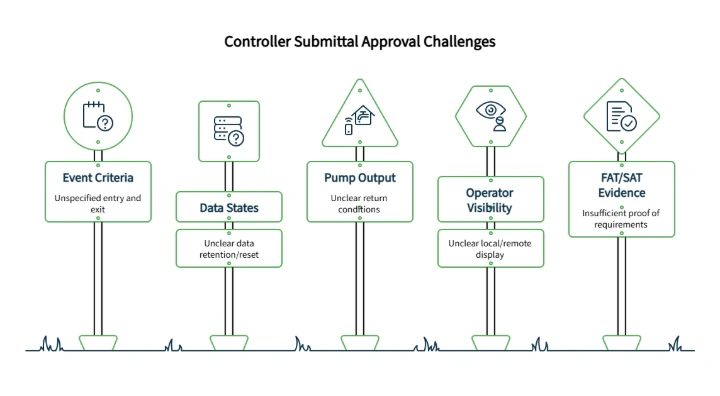
Which event classes are specified with observable entry and exit criteria?
Which data and operating states are retained, reset, or intentionally blocked after each event?
What must be true before any pump output command can return?
What will operators see locally and remotely, and in what chronology?
Which FAT and SAT evidence proves each requirement?
Do not accept "per manufacturer defaults" as a sufficient answer. Terms such as "automatic restart," "nonvolatile memory," "manufacturer standard," and "manufacturer defaults" do not resolve an unanswered question. Defaults are not an owner-approved operating philosophy and may change by model or firmware version. Older facilities frequently harbor unrecorded wiring changes, abandoned relay logic, or outdated schematics, rendering factory defaults dangerous to rely on without a physical audit.
Frequently Asked Questions
Should lift station pumps restart automatically after a power outage?
Sometimes. Automatic re-entry may be required under certain operating philosophies, delayed or staged under others, and prohibited without manual confirmation in specific conditions. Reliability alone does not determine safety or process acceptability. Define the answer through the approved sequence of operations, equipment constraints, backup-power capacity, wet-well conditions, and qualified review.
What controller settings should survive a power loss?
Separate configuration and setpoints from temporary operating states, overrides, pending commands, alarms, acknowledgments, runtime records, and clock state. The project must decide each category and verify the exact controller's behavior through current documentation and testing.
How should power-loss alarms behave if communications are unavailable?
Specify local indication, alarm persistence, event timestamps, buffering if the equipment supports it, retransmission on recovery, duplicate handling, and a communications-restored or return-to-normal indication. Product-specific behavior requires current documentation and end-to-end testing.
Which standards govern lift station restart behavior?
No single standard supplies a universal restart sequence. Applicable codes, wastewater design criteria, product standards, owner standards, and authority-having-jurisdiction (AHJ) requirements vary by project, jurisdiction, and adopted edition. Confirm current applicability with the engineer of record and AHJ before specifying or accepting any code-based requirement.
A specification, not a sequence
Resilience comes from explicit, reviewed, tested behavior, not from the word "automatic." Use the matrix with operations, electrical, controls, process, panel-design, manufacturer, and AHJ stakeholders before approving the controller submittal or acceptance plan. The goal is not to eliminate every risk; it is to make every requirement visible, agreed, and traceable to evidence.
Disclaimer: This article is for general informational and planning purposes only and does not constitute engineering, electrical, controls, safety, regulatory, or other professional advice. Power-event and restart requirements vary by site, equipment, operating philosophy, jurisdiction, and adopted standards. Have qualified project professionals and the applicable authority review requirements and test procedures before implementation.
Our Editorial Process:
OmniSite content is drafted from approved OmniSite source materials, reviewed for factual accuracy against product documentation and current website pages, checked for unsupported technical or quantitative claims, and edited for clarity for municipal wastewater and public works readers. Any claim involving safety, cybersecurity, reliability, warranty, pricing, reporting cadence, or technical specifications is traced to an approved OmniSite document or an authoritative external source.
By the OmniSite Insights Team
OmniSite manufactures control systems that help protect people and the planet by supporting municipal infrastructure monitoring for lift stations, water systems, wastewater systems, and airfield lighting, with a mission centered on protecting waterways, drinking water, and public safety through early warning of equipment issues.