📌 Key Takeaways
Treat every sensor failure as a full state transition, with defined detection, degraded operation, operator alerts, recovery, and testing.
Define Three Separate Layers: Separate the raw signal, declared fault, and controller state so each decision remains clear and testable.
Bound Every Degraded Mode: State what the controller trusts, retains, restricts, transfers, and stops under each approved failure condition.
Keep Events Distinct: Show alarms, acknowledgment, fault clearance, mode status, and restoration separately so operators cannot mistake awareness for recovery.
Control the Recovery Path: Require a stable, trusted signal and define who authorizes restoration before normal automatic control resumes.
Test the Full Lifecycle: Use a failure-response matrix to verify fault entry, degraded functions, alerts, intermittent faults, and return to normal.
A sensor failure demands a controlled state change.
Engineers, operators, owners, and controls teams can turn risk decisions into testable controller requirements using the framework below.
~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~ ~
A functional specification may define pump starts, stops, lead-lag rotation, and setpoint logic in precise detail, then reduce sensor failure to a single line: "Alarm on loss of level signal." That sentence tells the programmer to generate an alarm. It does not tell anyone what the controller should trust, which functions remain automatic, what the operator sees, when normal control may resume, or how the behavior will be tested.
A complete sensor-failure requirement resolves six connected decisions: how the fault is detected, how the controller declares it, what operating state results, how operators recognize the degraded condition, what criteria govern recovery, and how each transition will be verified during acceptance testing. The framework below organizes those decisions into a reusable requirements structure. It does not prescribe universal fallback logic; every entry depends on the station design, installed instrumentation, approved control narrative, and qualified engineering review. For context on connecting operational risks to testable requirements, see translating wet-well risks into controller requirements.
Define the Failure Condition Before Defining the Response
"Sensor failure" is too broad for a testable requirement. A 4–20 mA transmitter that drops to zero, a level reading frozen for hours, and two instruments that disagree each present different information to the controller. Treating every abnormal reading as the same fault produces one generic response where several distinct responses may be needed.
The specification should distinguish the raw signal condition (what the hardware reports), the declared fault (the controller's formal determination that a signal is untrustworthy), and the resulting controller state (the operating mode that follows). A fault declaration is the point at which the controller formally classifies a signal as untrustworthy and transitions to a defined response. These are separate events that belong in separate requirement statements.
At minimum, consider five signal categories:
Observed Condition | Possible Interpretation | Decision Still Required |
|---|---|---|
Failed: an explicit device, input, or loss diagnostic is active | Device fault, wiring loss, input failure, or unavailable source | Which diagnostic is authoritative, and when does it become a declared fault? |
Out of range: the value is outside an approved electrical or engineering range | Wiring issue, device fault, configuration error, or process exception | Which range applies, and what evidence distinguishes the causes? |
Stale: the value stops updating or repeats beyond an approved validity rule | Frozen output, interrupted update, or unavailable data path | What time or change criterion applies, and can the installed system detect it? |
Conflicting: two indications disagree beyond approved criteria | One signal may be wrong, or measurement authority may be uncertain | Does either signal have authority, and which functions may continue? |
Implausible: the value conflicts with process state or expected relationships | Sensor problem, incorrect context, or a real process exception | Which approved cross-check establishes suspicion, and what context is required? |
Not every controller or sensor combination can detect every category. The specification should identify which the installed hardware supports; unsupported categories should be documented as residual gaps. For guidance on inventorying sensors and interfaces, see lift station controller I/O planning.
Communications quality is a separate diagnostic dimension from physical range, staleness, disagreement, and process plausibility. A received value can look reasonable while its source or update path is unreliable. The project team should state which communications indicators affect signal validity without turning a sensor-failure requirement into a complete communications-failure specification.
Keeping these three layers distinct matters for review and testing. An observed signal condition is what the system receives. A fault declaration is the controller's evaluated conclusion under project-approved criteria. The controller state is the operating mode entered because of that conclusion. Combining all three into a single generic fault bit makes the requirement difficult to review, difficult to test, and likely to mask gaps that surface only during commissioning.
Classify What the Controller Knows and What It Does Not
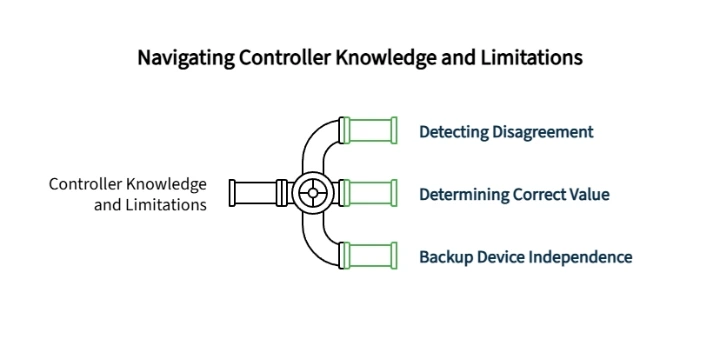
Detecting disagreement or implausibility does not automatically identify the correct value.
Hypothetical scenario: A continuous level transmitter reads six inches while a separate high-level float switch remains inactive. The transmitter could be reading low, the float could be stuck, or both could be accurate given differences in measurement location. This illustrates documentation questions, not recommended logic. Second hypothetical: Two redundant transmitters disagree beyond the expected tolerance, but the controller has no third instrument to identify which has drifted. In both cases, the specification should define signal authority (which measurement the controller treats as primary), available cross-checks, what control restrictions apply during disagreement, and who resolves the conflict.
Where the controller cannot determine the correct value, the specification should state whether it selects the more conservative reading, holds the last trusted value, restricts automatic functions, or transfers authority to the operator. The choice belongs to the project team.
If a backup device exists, the requirement should verify that its power source, field wiring, input channel, and logic path are genuinely independent. A shared circuit breaker, common conduit, or shared input module could disable both indications. For related reading on monitoring single points of failure, see fail-safe wet well monitoring strategy.
Define the Boundaries of Degraded Operation
Degraded mode is a named, bounded operating condition established by the project for use when normal information or functionality is unavailable. It is neither an assumed continuation of normal control nor an automatic shutdown. A retained function is a control, indication, protection, or communication function that the project team has determined may safely continue during a specific degraded condition.
"Continue operating" is incomplete unless it identifies trusted information, unavailable information, protections, and stopping or escalation conditions. "Stop automatic control" is equally incomplete unless it defines remaining local indication, manual authority, monitoring, and recovery path. Both are unfinished requirements without documented limits, and prescribing fallback logic before assessing station-specific risk shifts an operational-risk decision into an assumption that may never receive qualified review.
The specification should identify entry conditions, available and unavailable information, retained functions, restricted or inhibited functions, transferred functions or authority, permitted operator actions, escalation conditions, and exit authority.
Function Category | Status to Assign | Condition Governing Status | Operator Implication | Decision Owner |
|---|---|---|---|---|
Automatic level-based control | Retained, restricted, inhibited, transferred, or unavailable | Identify the credible information and approved entry condition | State what automatic authority remains and what is prohibited | Engineer and owner, with operations review |
Protection and independent backup functions | Retained, restricted, or unavailable | Verify independence and applicable failure dependencies | Identify which protections remain credible and visible | Engineer and approving authority |
Local indication and permitted manual actions | Retained, restricted, or unavailable | Define valid indications, access limits, and operating conditions | State what the operator can see and may do | Operations and engineer |
Remote alarms, notifications, and history | Retained, restricted, or unavailable | Define the available communications and platform functions | State delivery limits, escalation path, and records available | Operations, controls, and owner |
Each row defines a review category, not a project-specific status; the project team should complete entries using the approved control narrative and qualified engineering judgment. Compound failures deserve more than a brief note. If sensor validity also depends on communications or power, the specification should identify the interaction and route detailed behavior to the applicable communications-failure or power-restoration requirements, rather than leaving the overlap unaddressed. For the normal-operation baseline that degraded mode departs from, see pump sequencing and setpoint requirements.
The programmer can handle implementation details, but should not resolve unassigned operational-risk decisions. Programming converts approved intent into logic. The engineer defines that intent and its acceptance criteria, operations evaluates maintainability, alarm clarity, and operator burden, and the owner or approving authority accepts the operating boundaries and associated risk.
Specify Alarms, Operator Visibility, and Event History Separately
A fault alarm and a controller-mode indication serve different purposes. The specification should separate seven elements: fault detection, controller-mode indication (showing that displayed values may be untrustworthy), local annunciation, remote notification, acknowledgment, persistence (the alarm remains active until the condition is resolved regardless of acknowledgment), and historical recording.
Hypothetical scenario: An operator receives a sensor-fault notification and presses acknowledge. The alarm disappears from the active list, but the sensor remains faulted, the controller remains degraded, and displayed levels remain unreliable. Without separate definitions for these events, the operator may believe acknowledgment has resolved the situation. The specification should state what remains active while the condition persists, whether acknowledgment changes only presentation or notification behavior, and what happens if the signal becomes intermittent.
Three terms deserve clear, separate definitions in any sensor-failure specification:
Alarm acknowledgment confirms that a person is aware of the condition. Fault clearance confirms that the underlying abnormal condition no longer exists. Mode restoration returns the controller to normal automatic operation. These are three separate events with three separate authorities.
Operators need an unmistakable indication that a value is suspect and the controller is degraded. Displays should not present an invalid measurement or restricted mode as normal. Remote notification and local control continuity are separate functions. A callout reaching an operator's phone does not mean the controller has taken a safe automatic action at the station, and successful delivery does not establish that control authority remains valid.
Historical recording should capture distinct events across the full fault lifecycle: the observed condition, fault declaration, degraded-mode entry, acknowledgment, the declared fault becoming inactive, recovery authorization, and return to normal. The project must define the required timestamps, state transitions, retention period, and operator access according to its alarm philosophy and current system capabilities.
Product-specific alarm, callout, and history capabilities vary. According to its product page, OmniSite's GuardDog supports configurable alarms, callout lists, and historical data. OmniSite describes its system as logging alarm-triggering state changes and issuing configurable notifications through a callout list. These illustrate the types of configuration decisions a specification should address; verify current capabilities against installed product documentation before relying on any feature.
Define Recovery as Carefully as Failure Entry
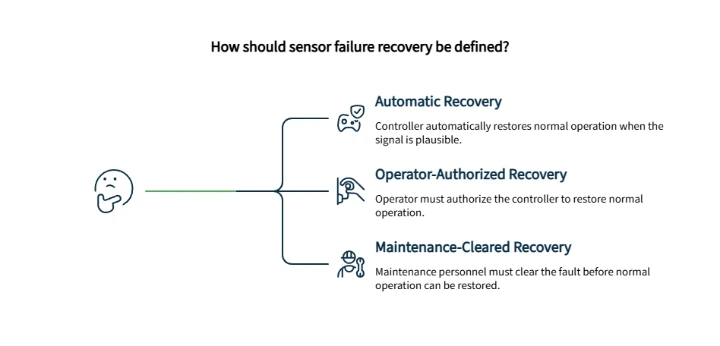
A signal returning to a plausible range does not automatically mean it is trustworthy.
Hypothetical scenario: A fouled level sensor drops below the valid range, triggers a fault, briefly returns to a plausible reading, then drifts again. If recovery is defined only as "signal returns to range," the controller cycles between normal and degraded operation on every transient, generating repeated alarms and unstable pump behavior.
The specification should address signal-return validation (what constitutes a valid signal and how long it must remain stable), reset authority (automatic, operator-authorized, or maintenance-cleared, as project choices), mode-restoration sequence, alarm clearance and event retention, and intermittent-fault handling (whether repeated faults trigger a lockout requiring maintenance clearance).
The project team must choose whether recovery is automatic, operator-authorized, or maintenance-cleared. The choice should reflect the station design, failure mechanism, diagnostic coverage, operating philosophy, and risk review. No universal selection or stabilization period applies to every installation.
Leaving recovery unstated transfers the decision to whoever programs or commissions the controller. System integrators are responsible for executing the requested logic, not making policy choices about acceptable station risk. If the specification is silent, the integrator, operator, and engineer may each assume a different restoration path.
Convert the Decisions into a Testable Failure-Response Matrix
Requirements that cannot be tested during commissioning may never be confirmed. Teams often verify normal sequences thoroughly while skipping transitions into and out of degraded operation.
The matrix below consolidates the framework into a reusable 11-column table. The hypothetical row prompts each field for one fault condition; every entry in a real matrix should be completed and reviewed by qualified stakeholders before acceptance testing.
Failure or Suspect-Signal Condition | Fault-Declaration Basis | Affected Measurement or Function | Resulting Controller State | Retained Functions | Restricted or Inhibited Functions | Alarm and Notification Behavior | Operator Indication | Recovery Condition and Authority | Verification or Test Method | Decision Owner |
|---|---|---|---|---|---|---|---|---|---|---|
Primary level transmitter output below valid range for longer than the project-defined persistence period | Signal below transmitter minimum for [project-defined] seconds, confirmed by controller input diagnostics where available | Wet-well level indication, lead/lag sequencing, low-level pump shutoff | Project-defined degraded mode | [Project team defines] | [Project team defines] | [Project team defines priority, annunciation, callout, persistence, acknowledgment] | [Project team defines degraded-state display] | [Project team defines validation, stability, reset type, restoration sequence, lockout] | [Project team defines simulated condition, expected state, expected alarms, retained/restricted functions, recovery action, pass/fail] | [Project team identifies] |
Each distinct fault condition should occupy its own row, completed using approved project documents.
Each acceptance test should state initial conditions, the simulated fault (using manufacturer-approved methods), expected controller state, expected alarms and indications, expected retained and restricted functions, recovery action, and pass/fail criteria. Do not bypass active safety interlocks or manipulate live equipment without an approved procedure. Representative test categories should cover fault entry, alarm behavior, retained-function verification, conflicting-indication handling, intermittent recovery, and return to normal.
Commissioning time is often limited, so the approved test plan should prioritize representative fault-injection and transition cases instead of confirming only normal sequences or individual inputs. Clear roles ensure this phase succeeds: the engineering team approves the test design, operations confirms it reflects real-world scenarios, the integrator executes the procedure, and the owner signs off on the final report. Subject to qualified controls and operations review, these categories validate the full fault-to-recovery lifecycle.
A Sensor Failure Is a State Transition, Not a Single Alarm
A sensor-failure requirement defines how the controller enters a degraded condition, what it may and may not do while degraded, how operators recognize the condition, and how normal operation is safely restored. A single alarm sentence cannot resolve that chain.
Choose one critical station signal and complete the failure-response matrix with engineering, operations, and controls stakeholders before the logic is finalized.
Frequently Asked Questions
Is a sensor-failure alarm enough?
No. An alarm does not define which control functions remain available, how the operator recognizes degraded conditions, what criteria govern recovery, or how the behavior will be tested.
Should normal mode return automatically when the signal comes back?
Automatic, operator-authorized, and maintenance-cleared recovery are all legitimate approaches. The choice depends on station design, fault characteristics, and the project team's approved operating philosophy.
Should a lift-station controller keep running if the level sensor fails?
No universal answer is safe. The specification should define behavior based on available independent signals, station design, operating risk, and qualified review.
Disclaimer: This article provides general educational information about lift-station controller requirements. It does not establish project-specific control logic, operating procedures, or regulatory compliance. Qualified controls and wastewater professionals should review requirements, settings, and test procedures for the applicable station and jurisdiction before implementation.
Our Editorial Process:
Content is developed from OmniSite source materials and reviewed for clarity, usefulness, and factual consistency. It is intended to help municipal and utility professionals evaluate monitoring and response-readiness options and should not replace site-specific engineering, electrical, regulatory, or safety guidance.
By the OmniSite Insights Team
The OmniSite Insights Team turns field-tested monitoring, alarm-notification, and municipal infrastructure knowledge into practical guides for wastewater, water, and remote equipment teams. OmniSite manufactures control systems that support early warning for lift stations, water systems, wastewater systems, and airfield lighting applications.